Tag: transformer architecture

-
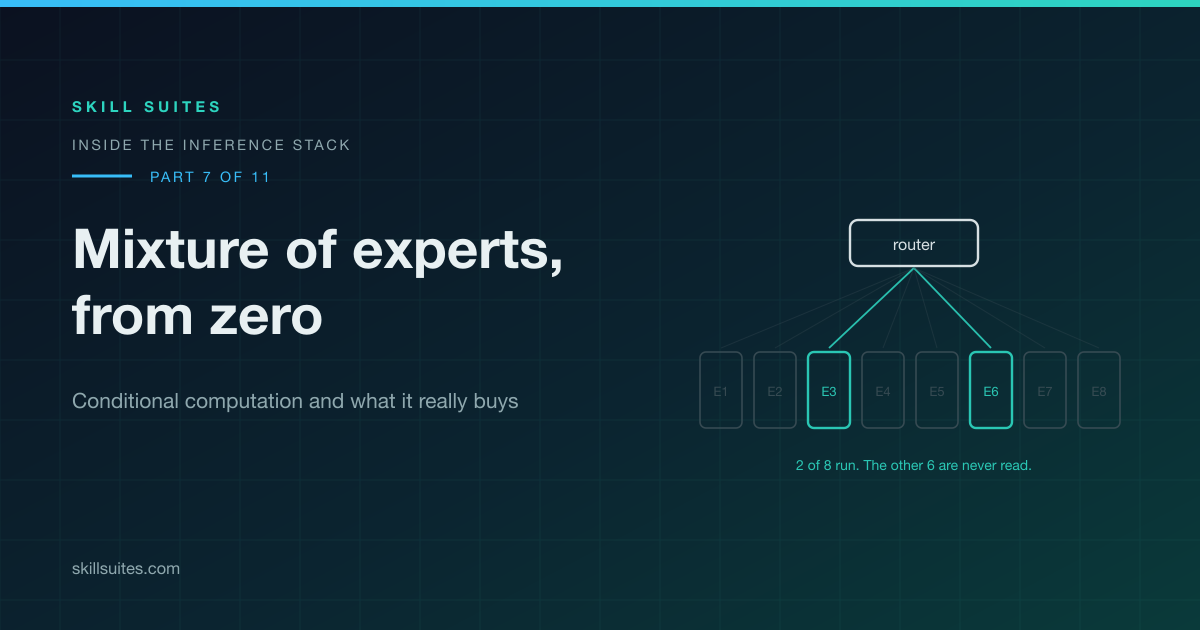
Mixture of Experts Explained: Conditional Computation From Zero
Mixture of experts explained from zero: the router arithmetic, total versus active parameters, and the three honest caveats most explanations skip entirely.
-
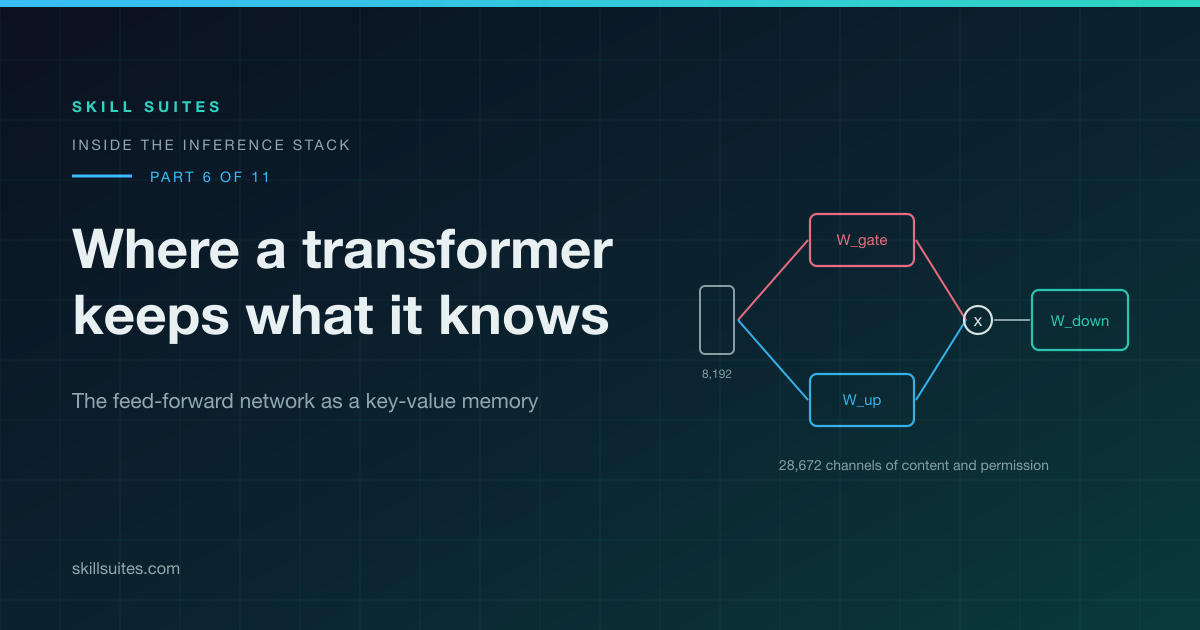
The Feed-Forward Network: Where a Transformer Keeps What It Knows
The feed-forward network holds 82 percent of a transformer block. Trace W_gate, W_up and W_down by hand, six channels at a time,…
-
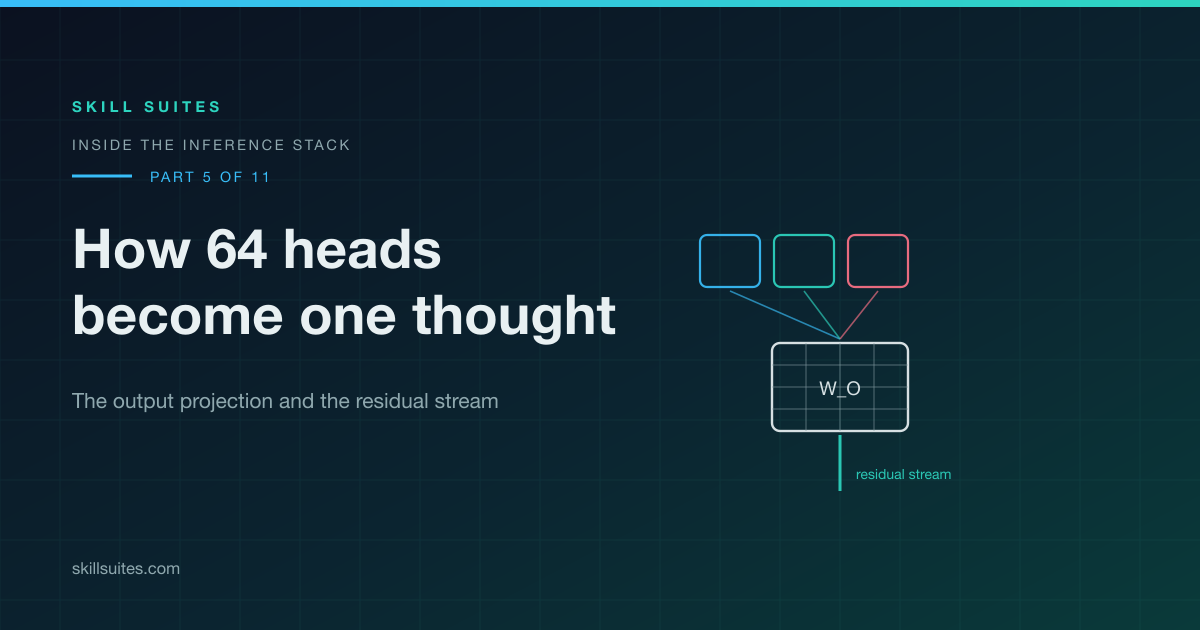
The Output Projection: How 64 Attention Heads Become One Thought
Work a full output projection by hand on a 6 x 6 grid, then see why W_O routes head findings and why…
-
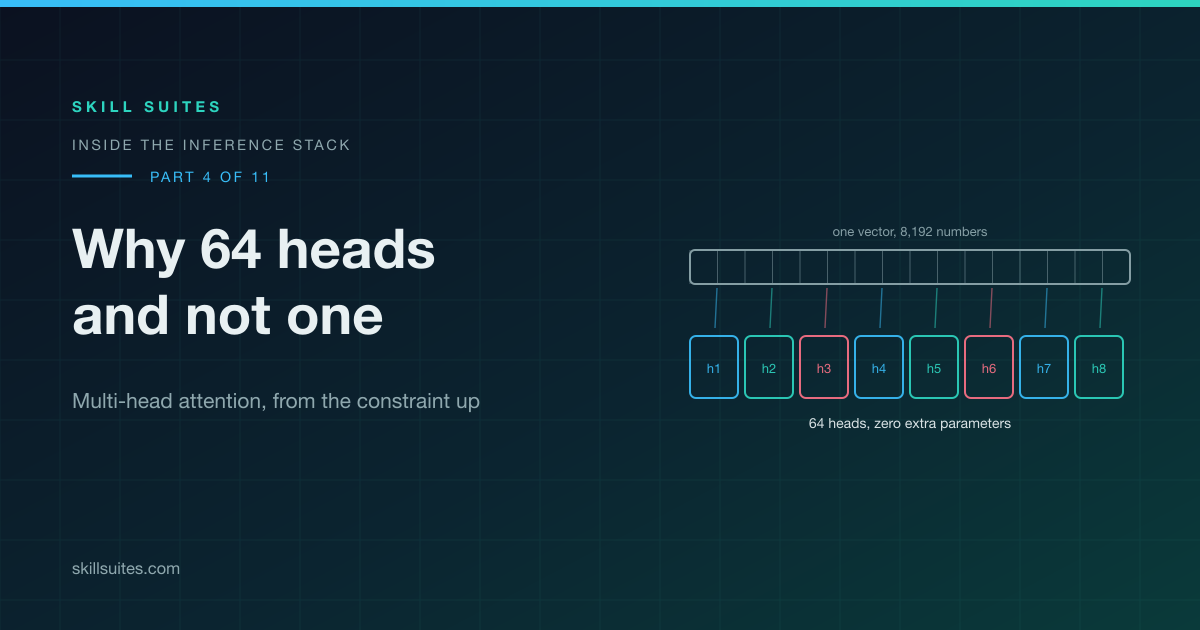
Multi-Head Attention Explained: Why 64 Heads Instead of One
Multi-head attention explained from first principles: why a single softmax is not enough, what a head actually is, and the KV cache…
-
How an LLM Answers a Question: The Complete Inference Path
Trace LLM inference end to end: seven tokens, an embedding lookup, 80 identical layers, sampling, and the memory bandwidth floor that caps…