Tag: KV cache

-
Activation Memory: Why the Forward Pass Costs More Than the Weights
Activation memory scales with batch, sequence, hidden size and depth, not parameters. The lifecycle, the quadratic attention trap, and every lever that…
-
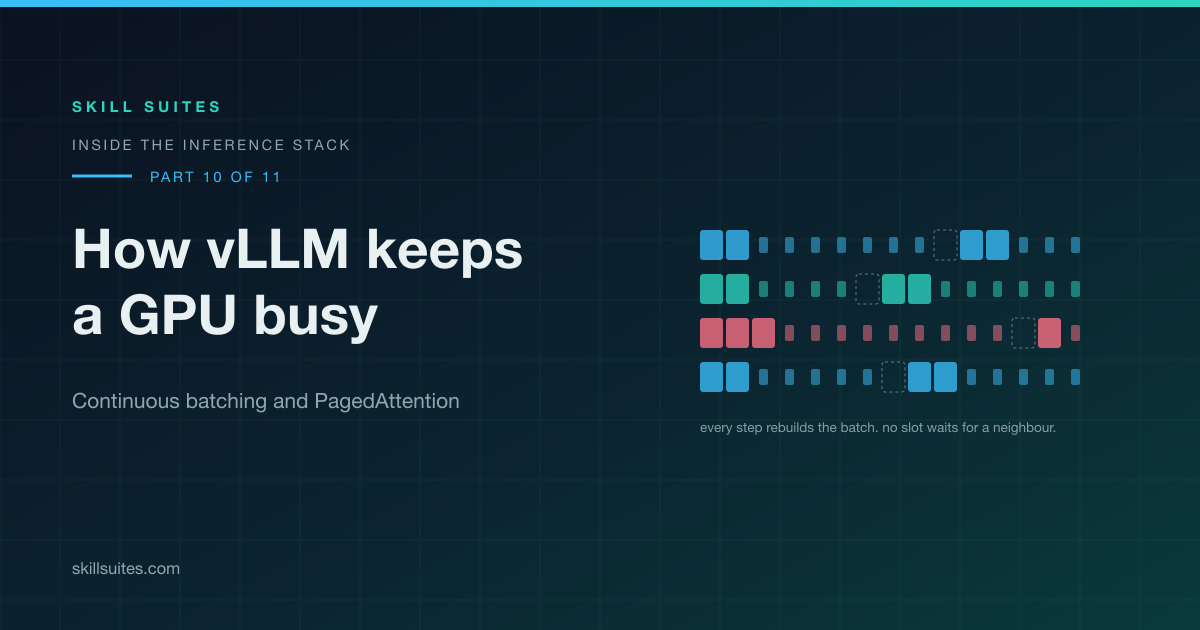
Continuous Batching and PagedAttention: How vLLM Keeps a GPU Busy
Continuous batching fixes scheduling and PagedAttention fixes KV cache memory. How vLLM keeps a GPU busy, with the arithmetic and the flags…
-
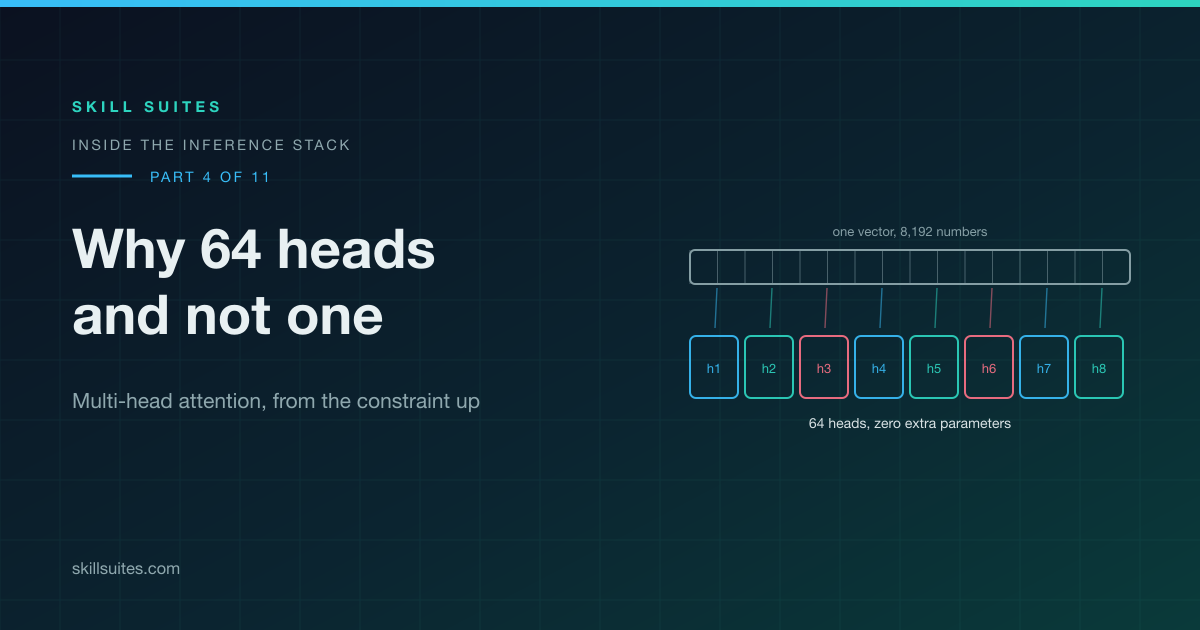
Multi-Head Attention Explained: Why 64 Heads Instead of One
Multi-head attention explained from first principles: why a single softmax is not enough, what a head actually is, and the KV cache…
-
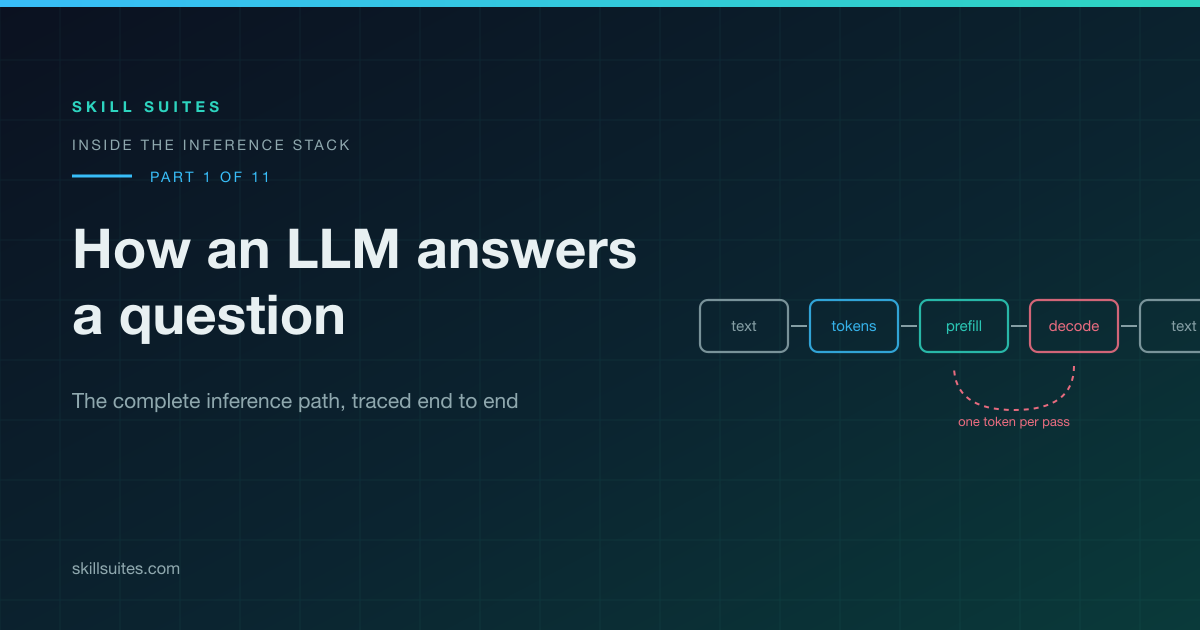
How an LLM Answers a Question: The Complete Inference Path
Trace LLM inference end to end: seven tokens, an embedding lookup, 80 identical layers, sampling, and the memory bandwidth floor that caps…