Tag: GPU serving

-
Continuous Batching and PagedAttention: How vLLM Keeps a GPU Busy
Continuous batching fixes scheduling and PagedAttention fixes KV cache memory. How vLLM keeps a GPU busy, with the arithmetic and the flags…
-
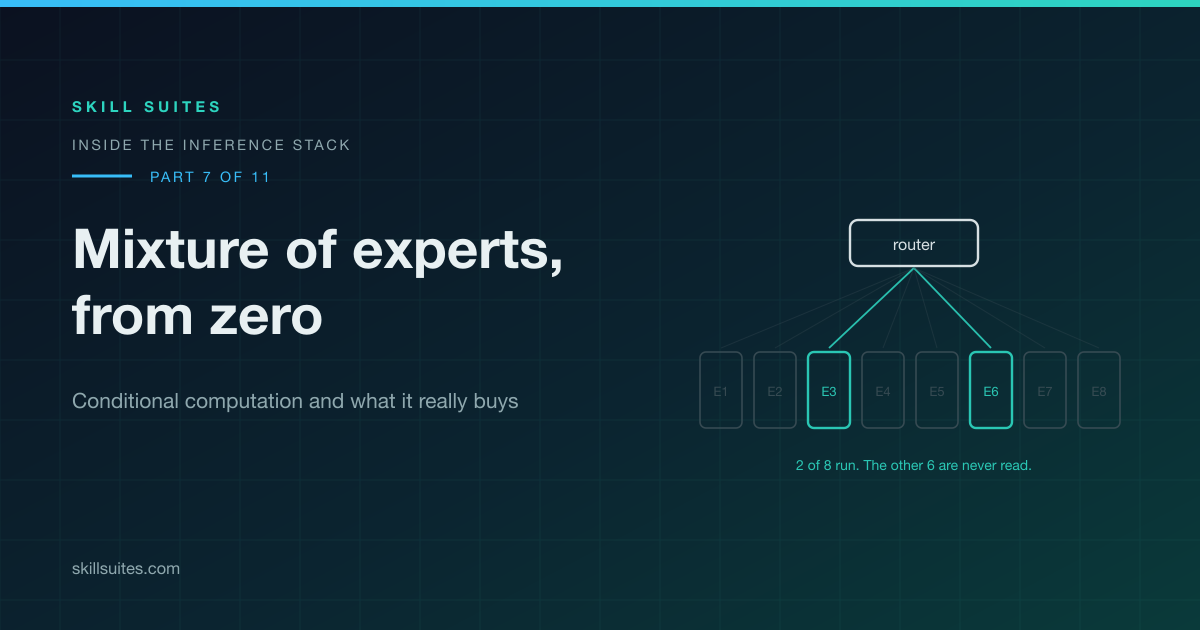
Mixture of Experts Explained: Conditional Computation From Zero
Mixture of experts explained from zero: the router arithmetic, total versus active parameters, and the three honest caveats most explanations skip entirely.
-
How an LLM Answers a Question: The Complete Inference Path
Trace LLM inference end to end: seven tokens, an embedding lookup, 80 identical layers, sampling, and the memory bandwidth floor that caps…