Tag: vLLM

-
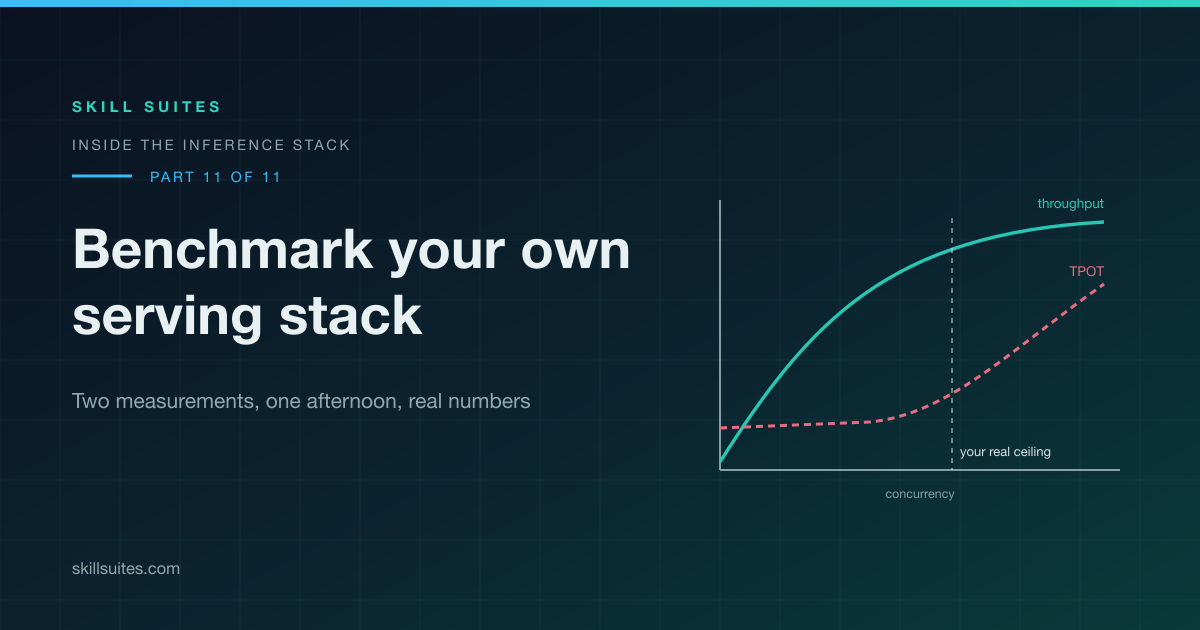
Benchmark Your Own LLM Serving Stack: Two Measurements, One Afternoon
Run an LLM serving benchmark on your own GPU in a single afternoon: measure the hardware roofline, sweep concurrency for TTFT and…
-
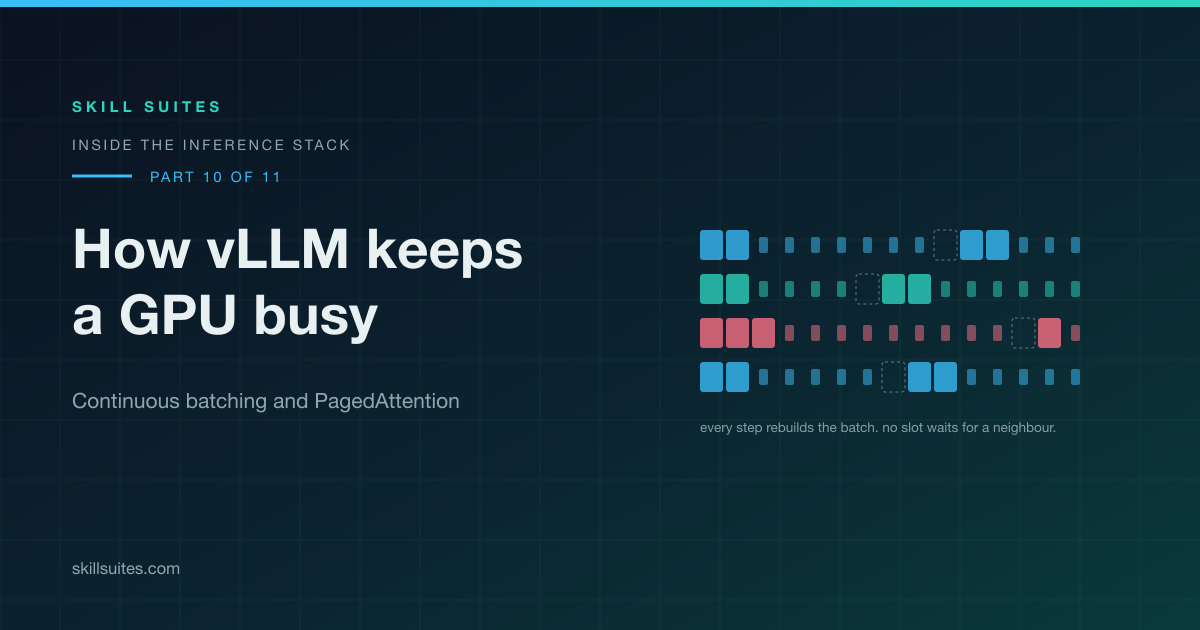
Continuous Batching and PagedAttention: How vLLM Keeps a GPU Busy
Continuous batching fixes scheduling and PagedAttention fixes KV cache memory. How vLLM keeps a GPU busy, with the arithmetic and the flags…